Moonshot's Kimi K3 Reaches Amazon Bedrock With Open-Weight Prompt Caching
Amazon Web Services added Moonshot AI's 2.8-trillion-parameter Kimi K3 to Bedrock on 18 September 2026, the first open-weight model there with prompt caching.

On this page
Key takeaways
- Amazon Web Services made Moonshot AI's Kimi K3 generally available on Amazon Bedrock on 18 September 2026.
- Moonshot describes Kimi K3 as the first open model to reach 2.8 trillion parameters, with native vision and a 1,048,576-token context window.
- Kimi K3 is the first open-weight model on Bedrock to support explicit prompt caching, where a cached prefix of at least 1,024 tokens is held for at least 30 minutes.
- The model is offered through a US geo profile (us.moonshotai.kimi-k3) for data residency and a global profile (global.moonshotai.kimi-k3) that routes to any supported commercial region and costs about 10% less.
- AWS's announcement relies on Moonshot's own figures; no independent benchmark data or cache pricing was published.
On 18 September 2026, Amazon Web Services said Kimi K3, the newest model from Moonshot AI, is generally available on Amazon Bedrock. AWS positioned it for coding and knowledge work, and singled out one detail as a first: Kimi K3 is the first open-weight model on Bedrock to support explicit prompt caching.
Related reading: OpenAI Says It Disrupted a Reasoning-Extraction Campaign Linked to Moonshot AI Associates · Mixture of Experts, Explained: Why the Biggest AI Models Activate Only Part of Themselves.
The scale is the headline. Moonshot describes Kimi K3 as its most capable model and the first open model to reach 2.8 trillion parameters. The model carries native vision and a context window of 1,048,576 tokens, which the company says suits long coding sessions across large repositories and multi-document work that includes scanned pages and screenshots.
Moonshot says Kimi K3 delivers roughly 2.5 times better scaling efficiency than Kimi K2. AWS repeats that claim, and attaches no independent measurement of its own.
What Kimi K3 is
Kimi K3 first appeared in July 2026 through Moonshot's own products: the Kimi app, the Kimi Work desktop app, the Kimi Code terminal tool and the company's API. Moonshot says it published the weights by 27 July. The Bedrock listing gives the model a managed distribution channel alongside those direct routes, and adds it to a Bedrock portfolio that already carries Kimi K2.5 and Kimi K2 Thinking.
The architecture is where the model gets unusual. According to Moonshot's GitHub model card, Kimi K3 is a mixture-of-experts design: 2.8 trillion total parameters, of which 104 billion are activated per token. It has 93 layers and 896 experts, with 16 selected per token plus two shared experts. The attention stack combines KDA with Gated MLA, and vision runs through a MoonViT-V2 encoder with 401 million parameters. Weights are stored in MXFP4 with MXFP8 activations.
"the world's first open 3T-class model" — Moonshot AI, Kimi K3 model card
How a mixture-of-experts model gets its speed: In a sparse MoE design, each token is routed to a small fraction of the network. Kimi K3 activates 104 billion of its 2.8 trillion parameters for any given token, so compute per token is far closer to a 100-billion-parameter model than to the full 2.8 trillion. The total parameter count sets capacity; the activated count drives serving cost.
That distinction matters for anyone reading the "2.8 trillion" figure as a proxy for cost. A dense model of that size would be impractical to serve at scale. A sparse one is still demanding, but the number that predicts inference cost is the 104 billion activated per token, plus the memory needed to hold the full weight set.
What Bedrock adds
Placing Kimi K3 on a hyperscaler changes the surrounding machinery more than the model itself. AWS says the model runs within the same security boundary as its proprietary models, with the same controls for access, encryption and auditing across a customer's model portfolio. For enterprises that evaluated open-weight models and worried about procurement, logging and compliance, that packaging is often the deciding factor.
The prompt caching feature is the more technical addition. Bedrock's explicit mode lets a developer mark the exact end of a reusable prompt prefix, after at least 1,024 tokens, by attaching a prompt_cache_breakpoint to supported input content. The tokens written into the cache are billed at a higher rate at write time, but they remain cached for at least 30 minutes. Later requests that match the prefix receive discounted input pricing and stop counting against input-tokens-per-minute quotas.
For long-running coding or agent workloads, that pattern fits squarely. Repository instructions, tool definitions and reference documents tend to be identical across calls, so caching them removes repeated input cost and latency. AWS did not publish the exact cache pricing, which makes the savings hard to model before a bill arrives.
Where to find it: Kimi K3 is reachable in the Bedrock console under Test > Playground, or programmatically through the bedrock-runtime endpoint. Bedrock exposes it through the native Invoke and Converse APIs and through OpenAI-compatible Responses and Chat Completions APIs. The OpenAI-compatible surface is what lets tools such as the Kimi Code CLI point at Bedrock with a changed base URL.
Caching of this kind has become a competitive feature among model providers, because it attacks the part of agentic inference that scales with repetition rather than with task size. When an agent re-reads the same repository or policy document on each step of a long run, the input side of the bill can dwarf the output side. A cache breakpoint lets the provider charge once for writing that prefix and then a lower rate for every reuse, which changes the unit economics of a workflow that would otherwise be uneconomic to automate.
Two cross-Region inference profiles are on offer. us.moonshotai.kimi-k3 keeps inference inside the United States for data residency requirements. global.moonshotai.kimi-k3 routes a request to any supported commercial AWS region and costs roughly 10% less, according to TPS Report. The trade is between jurisdictional control and price, and AWS leaves the choice to the customer.
The open-weight economics
Kimi K3 is the latest entry in a portfolio shift at Bedrock. Since 2025 the service has added open-weight models from DeepSeek, Google, MiniMax, Mistral AI, Moonshot AI, NVIDIA, OpenAI and Qwen. In 2026 AWS layered platform-level capabilities on top: tool calling, structured output, reasoning, response streaming, and the Responses and Chat Completions APIs. New open-weight models inherit those features rather than requiring per-model integration work.
What AWS has not said: The announcement describes Kimi K3 with Moonshot's own language and figures Unite.AI also noted. AWS published no independent benchmark results for coding, reasoning or vision, and it did not disclose cache write or cache read pricing. Treat the capability and efficiency claims as vendor claims until third parties test the model.
Open weight is easy to misread as open source or as free. It is neither. Publishing weights lets others download, fine-tune and self-host the model, subject to the license Moonshot attaches. It does not lower the cost of running a model this large. A 2.8-trillion-parameter sparse model still needs substantial accelerator memory and a serving stack, which is precisely the problem a managed endpoint like Bedrock is meant to absorb.
The economics of open weight have shifted in recent years. For most teams, self-hosting a frontier-class model is more expensive than renting API access, and the real benefit of open weights is optionality: the ability to move between providers, fine-tune, or keep data inside a controlled environment. Bedrock's version of that story is that a customer can use a Moonshot model under the same governance umbrella as Anthropic's or Amazon's own.
Prompt caching fits that commercial logic. Inference providers compete partly on input-token cost for agentic workloads that resend large context on every step. Offering explicit caching, even without published rates, signals that AWS expects Kimi K3 to be used in long, repetitive, tool-heavy sessions rather than one-shot chat.
The open-weight market has also grown more crowded at the top end. Models in the hundreds of billions of parameters are now routine, and a 2.8-trillion-parameter release raises the ceiling for what a downloadable model can claim to be. That scale carries a practical consequence: fewer organizations can serve it themselves, which pushes even open-weight usage toward managed endpoints and makes cloud distribution more valuable, not less. The paradox of a large open model is that its size can make it more dependent on the very platforms that host it.
Caveats worth naming
The gap between the announcement and verified performance is wide. Moonshot's parameter count, its 2.5x efficiency claim and its "first open 3T-class model" phrasing are the company's own characterisation. Moonshot has not released independent third-party evaluations for this release, and AWS does not supply any. Parameter count is not a benchmark; it says nothing about how the model codes, reasons or reads documents compared with rivals.
The pricing picture is also partial. Input and output token rates exist on the Bedrock pricing page, but cache write and cache read rates were not published in the launch material. Without them, the headline caching feature cannot be converted into a cost estimate, which matters for the long-context workflows the model targets.
There is a distribution angle too. Moonshot is a Chinese lab, and Western enterprises increasingly weigh origin and licensing terms when choosing a foundation model. "Open weight" does not mean the license is unrestricted, and teams that plan to fine-tune or resell should read the terms rather than assume permissive use.
What to watch
Three things would turn this from an announcement into a decision. First, published cache pricing, which would let teams model the cost of agentic workloads that the feature is built for. Second, third-party benchmarks on coding and long-context retrieval, which would test Moonshot's claims against models already on Bedrock. Third, adoption signals, such as whether coding tools and agent frameworks add Kimi K3 as a first-class option or treat it as one more endpoint.
The wider question is whether hyperscaler distribution becomes the default path for large open-weight models. When a model is available both as downloadable weights and as a governed cloud service, the cloud service often wins with enterprise buyers who value procurement and audit over control. If Kimi K3 follows that pattern, the part of the launch that determines its adoption will be the caching meter that AWS has not yet priced.
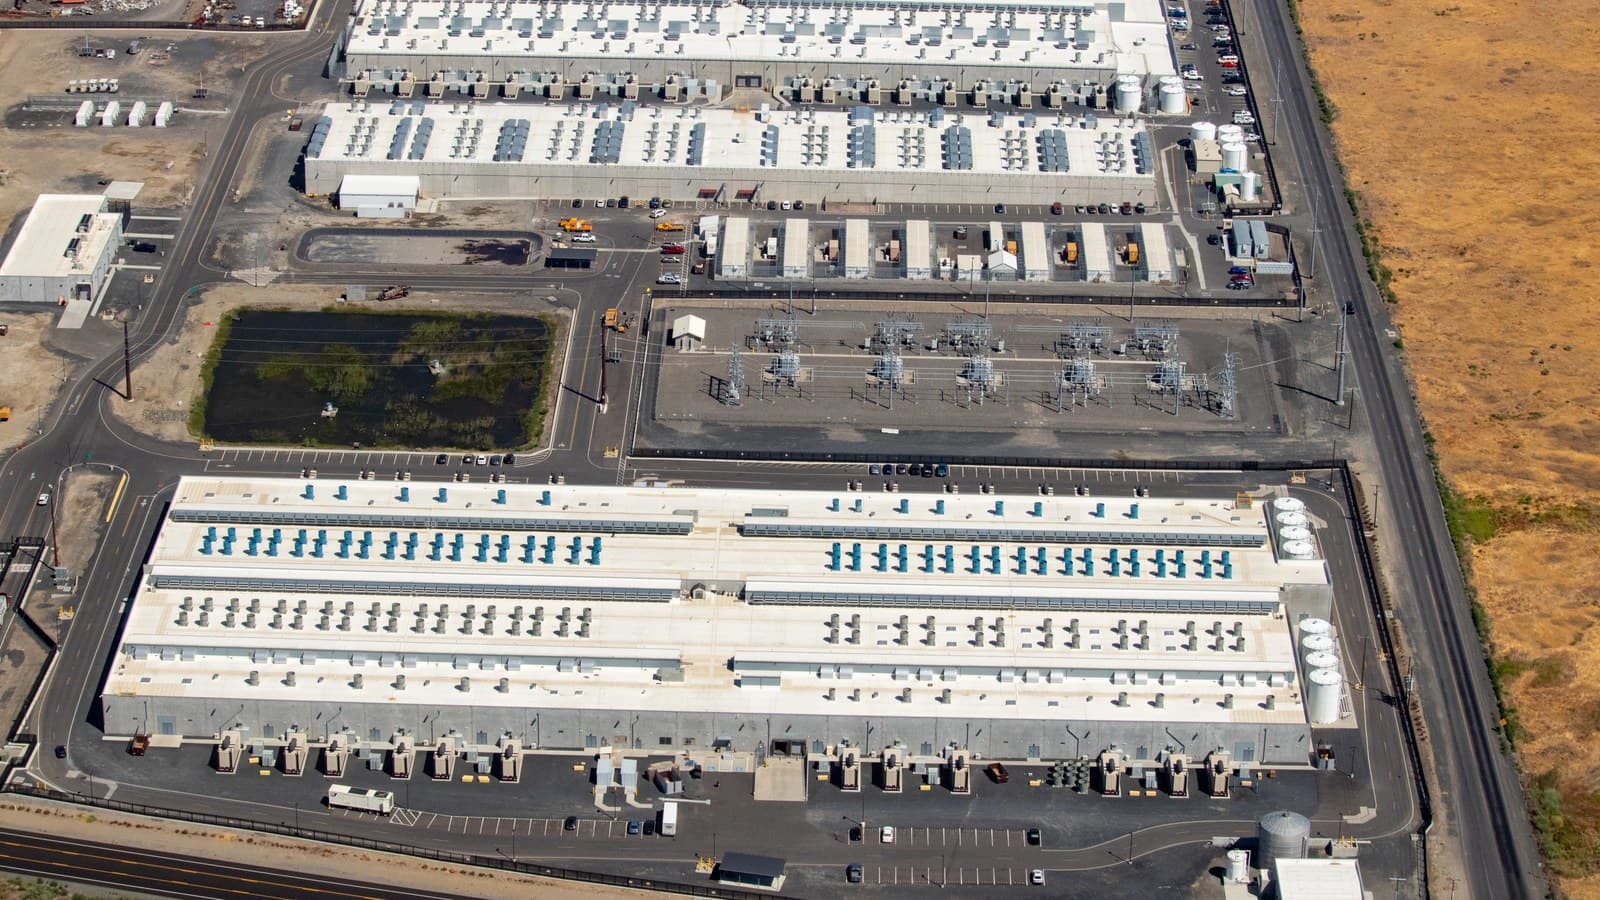
Cover: Amazon AWS us-west-2 data center, "Amazon AWS us-west-2 beach AZ.jpg" by Tedder via Wikimedia Commons, licensed CC BY-SA 4.0 (cropped to 16:9).
Tags
Frequently asked questions
- What is Kimi K3?
- Kimi K3 is a large open-weight model from Moonshot AI. Moonshot describes it as its most capable model and the first open model to reach 2.8 trillion parameters, with native vision and a context window of roughly one million tokens.
- What is explicit prompt caching on Amazon Bedrock?
- It lets developers mark a reusable prompt prefix, after at least 1,024 tokens, with a prompt_cache_breakpoint. Cached tokens are billed at a higher write rate but held for at least 30 minutes, and matching later requests get discounted input pricing and do not count against input-tokens-per-minute quotas.
- How do you access Kimi K3 on Amazon Bedrock?
- Through two cross-Region inference profiles: us.moonshotai.kimi-k3 for US data residency, or global.moonshotai.kimi-k3, which routes to any supported commercial region for about 10% less. It is available in the Bedrock console playground and through the bedrock-runtime endpoint.
- Is Kimi K3 free because it is open weight?
- No. Open weight means the model weights are published, but running a 2.8-trillion-parameter model still requires substantial compute, and on Bedrock it is a metered service with input and output token pricing.

TPW Editorial
Editorial Team
TechPastWeek's editorial team reports and edits every story we publish. We research each piece against primary and credible secondary sources, and a human editor reviews and signs off before it goes live.