Nvidia Opens CUDA to Windows on Arm and Gives Developers a Rubin Preview
Nvidia's CUDA Toolkit 13.4 reaches general availability with native Windows on Arm development, a preview of the Rubin GPU architecture, and a rebuilt MPS.

On this page
On September 9, 2026, Nvidia released CUDA Toolkit 13.4, and in doing so it closed a gap that had kept its developer platform off an entire class of computers. The toolkit extends CUDA development to Windows on Arm, something Nvidia had never shipped before, and it also opens an early path to Rubin, the company's next-generation GPU architecture. The public download is CUDA 13.4.1, which replaces the developer preview Nvidia posted in July. (Nvidia Technical Blog, VideoCardz)
Related reading: DeepSeek Open-Sources a Software Stack for Huawei's Ascend Chips, Aiming at CUDA · Nvidia's DSX POD Turns an AI Factory Into a Shipping Container.
The Windows on Arm piece is the headline. CUDA has run on Arm hardware for years, but only through Linux, on Jetson modules and Arm64 servers. Native Windows Arm64 was the missing target, and its absence kept most of the CUDA-dependent stack, from PyTorch and TensorRT to professional rendering and simulation tools, off Arm-based Windows machines. Nvidia's blog describes the release as extending CUDA "to the Windows on Arm platform," noting that applications had "long been supported on Arm platforms through Linux."
A first-party toolchain arrives
Developers have two ways in. They can build CUDA applications directly on a Windows Arm64 system, or cross-compile for Arm64 from the Windows x86-64 toolkit. For teams that do not yet own Arm hardware, the second route is the practical one, and it is the same order of operations the industry saw a decade ago when Arm servers were first pitched as a second architecture for data centers.
Nvidia lists Windows Arm64 support across components including NVCC, the CUDA runtime, cuBLAS, cuFFT and the Nsight developer tools, according to VideoCardz. Guru3D reports the same set and adds that the toolkit's core math libraries gain functional Windows on Arm support for what Nvidia calls the N1X laptop ecosystem, the Arm-based platform behind the RTX Spark machines announced at Computex in June.
The driver is no longer in the box
Starting with CUDA 13.4, Nvidia's SDK installers no longer bundle a GPU driver. Linux users now install a separate Developer Driver (R616) from Nvidia's download page, a change the developer preview notes flagged in July. Windows users were already on a separate driver path.
Why opening CUDA to Windows Arm matters
CUDA is Nvidia's strongest lock-in. Competing acceleration stacks exist (AMD's ROCm and HIP, Intel's oneAPI and SYCL, Apple's Metal and MLX), but none carries CUDA's installed base or the library support that AI frameworks assume by default. Bringing that stack to Windows on Arm is less about adding a checkbox and more about extending the moat into the one PC category where Nvidia's software had no native presence.
That matters because the Arm PC developer base is finally big enough to build for. Apple's M-series normalized Arm laptops for creative and scientific work, Qualcomm's Snapdragon X line pushed Windows on Arm into the mainstream, and Microsoft has spent years improving its Arm64 tooling and Arm64EC translation ABI. Every one of those machines could run an Arm operating system, but a CUDA application compiled only for x86 obtained no GPU acceleration on them. Windows on Arm had CPU and integrated-graphics story but no first-party path to Nvidia's compute platform.
Nvidia is timing the software to its own silicon. RTX Spark, the company's Arm-based PC platform, pairs Grace CPU cores with a Blackwell-derived GPU. Nvidia's own developer guidance tells teams to start porting now on whatever Windows on Arm hardware they already have, then validate on RTX Spark once retail systems and drivers are available. Shipping the toolchain before the hardware is the opposite of the pattern that sank earlier Windows on Arm waves, when machines arrived with software that had not been rebuilt for them.
Rubin arrives as a preview, not a product
The second headline is Rubin. CUDA 13.4 adds what Nvidia calls "functional support for the NVIDIA Rubin architecture (compute capability 107) as a preview," letting developers compile and test against the architecture before "CUDA support for Rubin reaches general availability in a future release of the CUDA Toolkit."
The mechanism is concrete and easy to miss. Nvidia's compiler gains an SM_107 target, and the updated PTX instruction set includes some Rubin capabilities, which means libraries and frameworks can start building Rubin-ready binaries and CI pipelines now. Hardware Premium makes the same distinction explicit: Rubin in 13.4 is a functional preview, with general availability reserved for a later toolkit.
Preview is not GA
Rubin support here is a developer preview. There is no shipping Rubin hardware behind it, Nvidia's release notes describe the preview as pre-release software, and the company explicitly cautions against using preview builds for production, certification or benchmarking. Treat any early Rubin performance number with the same suspicion you would apply to a July beta.
For the roadmap, the signal is about sequencing rather than speed. CUDA support normally accompanies a new architecture at or near launch, so a preview months ahead of general availability gives library maintainers, framework authors and the usual long tail of CUDA applications a head start. It also tells the market which architecture Nvidia wants the ecosystem aligned around next, at a moment when its current data-center parts are still ramping.
MPS V3 and the shared-GPU problem
The release also modernizes Multi-Process Service, the mechanism that lets several processes share one GPU without simply serializing them. MPS V3 replaces the older control model with a scriptable command-line interface, named server instances, and namespaces for organizing concurrent workloads. It adds TOML configuration, streaming-multiprocessor partition controls and cgroup-integrated GPU memory limits.
The practical effect is programmatic partitioning: compute performance, memory boundaries and execution priority can all be defined in configuration rather than arranged by hand. For containerized and orchestrated environments, where several tenants or jobs may want the same accelerator, that is the difference between best-effort sharing and enforceable isolation. Nvidia frames it as a way to raise utilization without giving up resource guarantees, and it points developers to a new MPS V3 quickstart.
There are smaller additions aimed at the same problem of moving and placing data efficiently. CUDA Compute Fabric Transport offers a transport-centric API for communication libraries to move data across NVLink fabrics using named logical endpoints and asynchronous put, get and reduction operations, rather than mapping every remote allocation into a process's address space. Locality domains expose groups of SMs and device memory that can be co-located, and a new API for querying unified-memory residency, cudaMemGetLocationInfo, lets performance-sensitive code see where managed memory actually sits before scheduling work.
Libraries, Python and profiling
The supporting cast got updates too. cuBLAS adds double-precision performance through fixed-point emulation using the Ozaki-II scheme, and cuBLASLt gains dynamic scheduling for Grouped GEMM workloads on Blackwell data-center GPUs, aimed at the many-group patterns common in mixture-of-experts models. CCCL 3.4 ships a warp-specialized cub::DeviceScan for Blackwell that Nvidia says reaches up to 92 percent memory-bandwidth utilization, up from roughly 50 percent in the previous implementation, alongside single-call CUB APIs and C++ Standard Library parallel algorithms under a cuda::execution::gpu policy.
CUDA Python expands in two directions. cuda.core 1.1.0 adds texture and surface programming, NUMA-aware managed memory, richer graph workflows and .pyi type stubs that give IDEs and coding agents real signatures. cuda.compute 1.1 adds ahead-of-time compilation of CCCL algorithms for multiple GPU architectures, with serialized artifacts that can be shipped and deserialized on target hardware without a recompile.
On the tools side, Nsight Systems 2026.5.1 adds support for CUDA 13.4, Rubin GPUs and Windows on Arm, and carries a long list of profiling additions: CPU metric sets, PyTorch shape tracing, network and storage analysis recipes, and a plugin framework that can initialize before an application starts. Nsight Python 1.0 automates kernel profiling from a Python script, and Nvidia is also pitching an AI layer, including a hosted CUDA MCP server that connects coding agents to CUDA documentation.
Nvidia is not selling a faster GPU here. It is selling reach: a CUDA toolchain that can now target the Arm laptops its silicon is heading into, and a compiler that can already see the architecture after next.
Caveats and what to watch
The obvious caveat is that most of this is groundwork. CUDA 13.4 will not make an existing GPU faster, and Windows on Arm support is a platform investment whose payoff depends on hardware that is not on shelves yet. The July preview came with rough edges that Nvidia documented for developers, including slower transfers over pageable memory and, in some PyTorch build workflows, GPU timeouts or system restarts. The September general-availability release is the version meant to be used, but the ecosystem around it, from cuDNN to framework wheels, will take time to fill in.
The Rubin preview deserves its own caution. Preview support lets code compile and run where drivers and compatible hardware allow, but it is not a launch, and Nvidia has not committed to a date for GA. Anyone reading a benchmark derived from preview builds should assume the numbers are non-representative, which is exactly what Nvidia's preview terms state.
What to watch next is concrete. First, whether the first RTX Spark systems arrive with the CUDA stack this toolkit enables, since a toolchain ahead of its hardware only pays off if the hardware follows. Second, how quickly major frameworks publish Windows Arm64 wheels that use it, which is the real test of whether "CUDA on Windows on Arm" becomes an everyday option or stays a developer preview in practice. Third, the graduation of Rubin from preview to general availability, which will mark the point at which the architecture's toolchain is considered stable. For now, the software is ready before the silicon, and that ordering is deliberate.
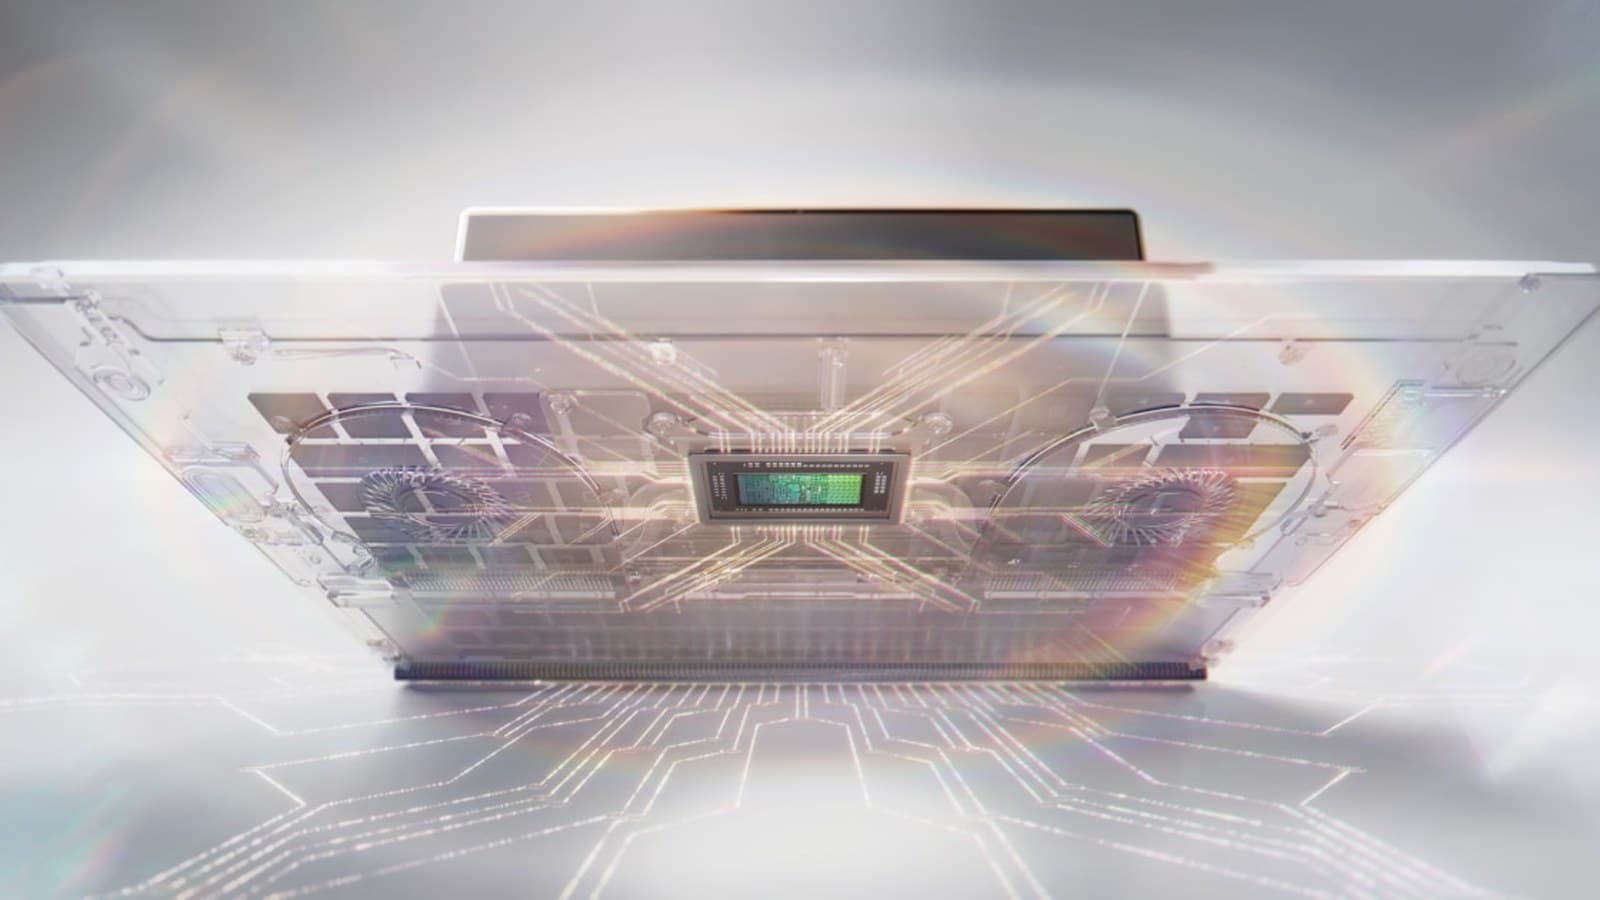
Cover image: official Nvidia RTX Spark product render (company-distributed product asset from nvidia.com), cropped to 16:9.
Cover image: official Nvidia render of the RTX Spark laptop. Image: Nvidia.
Tags

TPW Editorial
Editorial Team
TechPastWeek's editorial team reports and edits every story we publish. We research each piece against primary and credible secondary sources, and a human editor reviews and signs off before it goes live.